Featured · Final Year Project
Teaching a game agent not to forget
Game agents trained through self-play can forget strategies they previously learned. I built a Java and Python experiment in MicroRTS that kept agents competing against historical versions of themselves, with more weight given to opponents they struggled to beat.
Across 80 million training steps, historical self-play reduced prolonged performance collapses and produced consistently higher TrueSkill ratings than standard self-play.
Results at a glance
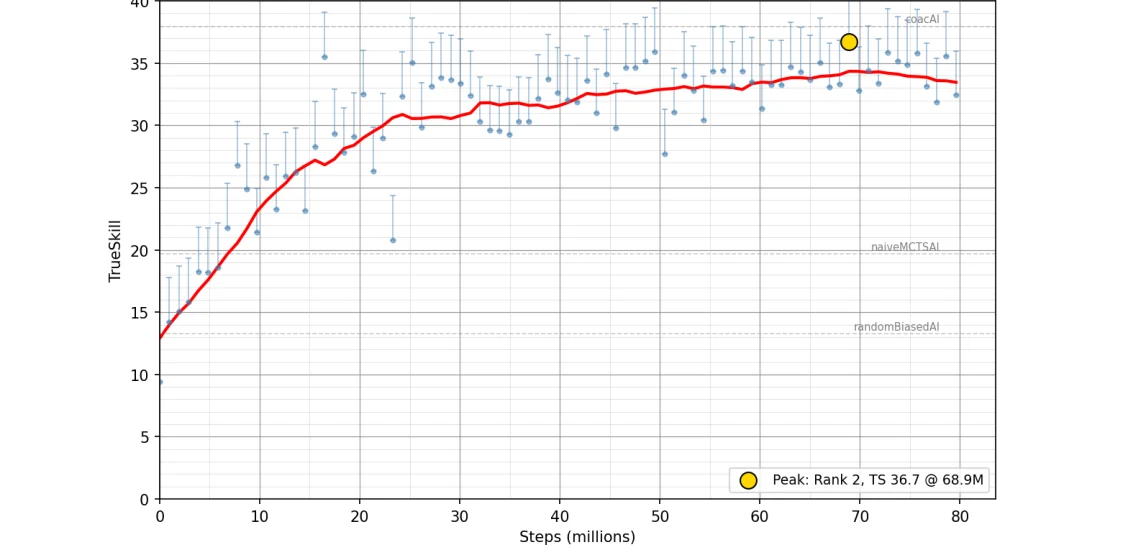
Two runs using the same agent and parameters over ~80 million steps: one trained through standard self-play, the other also faced historical checkpoints. The video shows the trained agent (blue) playing against CoacAI.
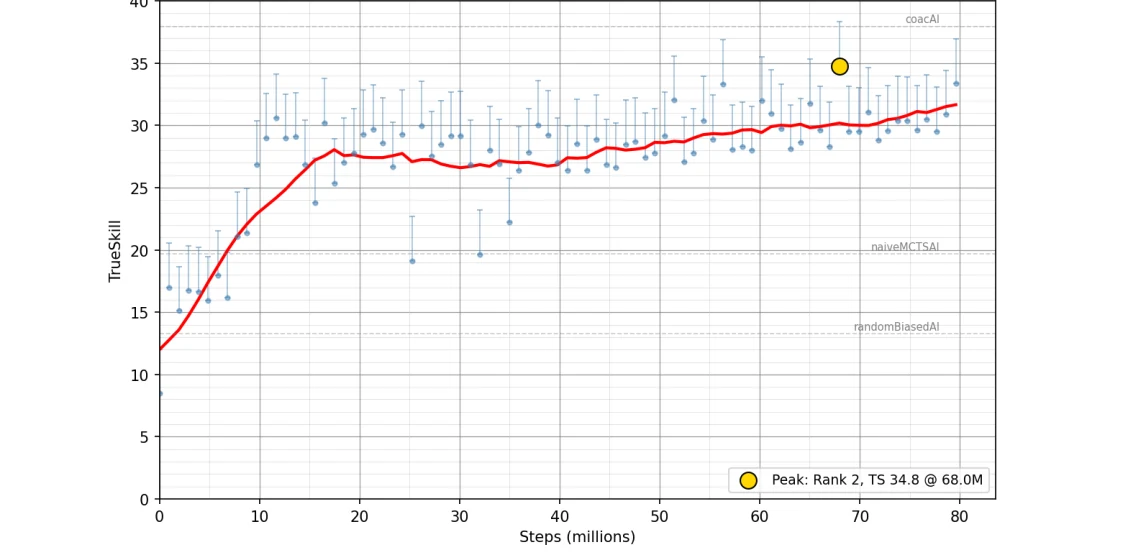
Without historical checkpoints: the rating plateaus around 27–31 and repeatedly dips as the agent overwrites its own best strategies. Peak: TrueSkill 34.8.
With historical checkpoints: the rating keeps climbing and holds consistently higher through the second half of training with a peak of 36.7, closing in on the competition bot CoacAI (top dashed line).
Evaluation charts taken directly from the report with TrueSkill rating vs training steps, 83 evaluations per run. Dashed lines mark fixed reference bots.